Models & Pricing
Packs with slower-burn rates. 10× Everyday and 6× Frontier value.
Model pages list context window, endpoints and capabilities. The live catalog is the source for which ids are on the key.
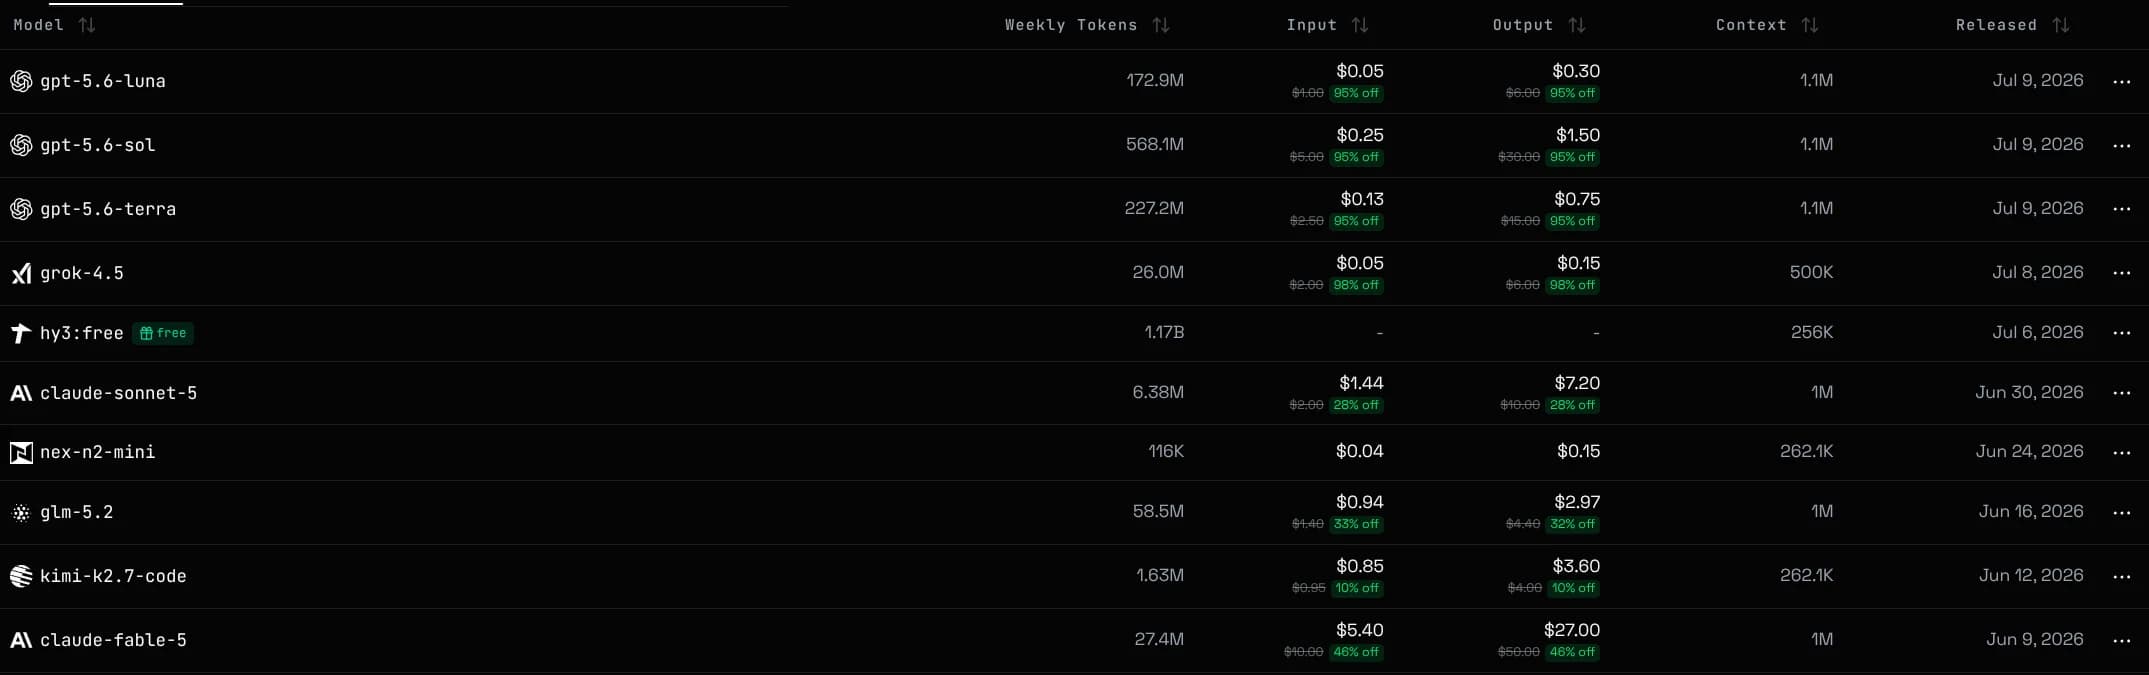
Everyday workhorse models burn at 10× value (0.1× lab list), while Frontier reasoning giants burn at 6× value (1/6th lab list). Promo and off-peak stickers are ignored.
New here? Getting a key and sending a first request takes a minute in Quickstart
Inferio token prices burn at fixed fractions of the published first-party lab list: 10× value on Everyday models (0.1× list) and 6× value on Frontier models (1/6th list). Image, video, and audio follow the lab's per-unit sticker.
The Pricing page is where you buy packs and read the estimated monthly turns per model.
A pack is one $10 pool for every model on the key. It is not a separate allowance per model.
Token prices burn at 10× value on Everyday models and 6× value on Frontier models. Because agentic coding turns are predominantly cached context, your pack lasts thousands of turns.
On one pack, Everyday models deliver 50,000–250,000 coding turns. Frontier reasoning models deliver 1,700–11,500 deep coding turns.
Turn estimates are based on a realistic agent coding interaction: 1,000 prompt tokens, 50,000 cached context tokens, and 200 output tokens. Pack balance divided by cost per turn yields the estimated turns.
Worked example: GLM-5.3-Flash list is $0.15 in / $0.03 cache / $0.50 out. As a Frontier model (6× value), the effective rates are 1/6th ($0.025 in / $0.005 cache / $0.083 out), costing ~$0.00029 per turn. A single $10 pack covers ~34,285 turns.
The live model table sits on Pricing.
On models whose lab publishes a cached-input rate, repeated prompt prefixes bill at that cache rate scaled by our tier multipliers. We do not invent a cache sticker.
Caching is automatic when the upstream supports it. Long stable system prompts benefit most.
Requests fail over to the next provider group when one is rate limited or down. A model leaves the catalog only when every channel is out.
A model disappearing under load is expected. It returns within minutes once a channel recovers.
Keys that pin provider groups fail over only within their pinned groups, see Group Pinning
To get pinged the moment it comes back, watch it in Notifications